Support or surveillance? Learning analytics and the questions that decide
Here is a pitch that is hard to argue with. What if you could tell, weeks before a student failed or dropped out, that they were heading that way, and step in while there was still time to help? No more finding out in the exam results that someone had been drowning since October. Just an early signal that lets you reach the people who need reaching.
That is the promise of learning analytics, and it is a good one. By pulling together the digital traces students leave – logins to the virtual learning environment, attendance, library use, assignment submissions – these systems build a picture of who is engaging and who is slipping, and flag the ones who might need support. Used well, it catches people who would otherwise have fallen through the gaps.
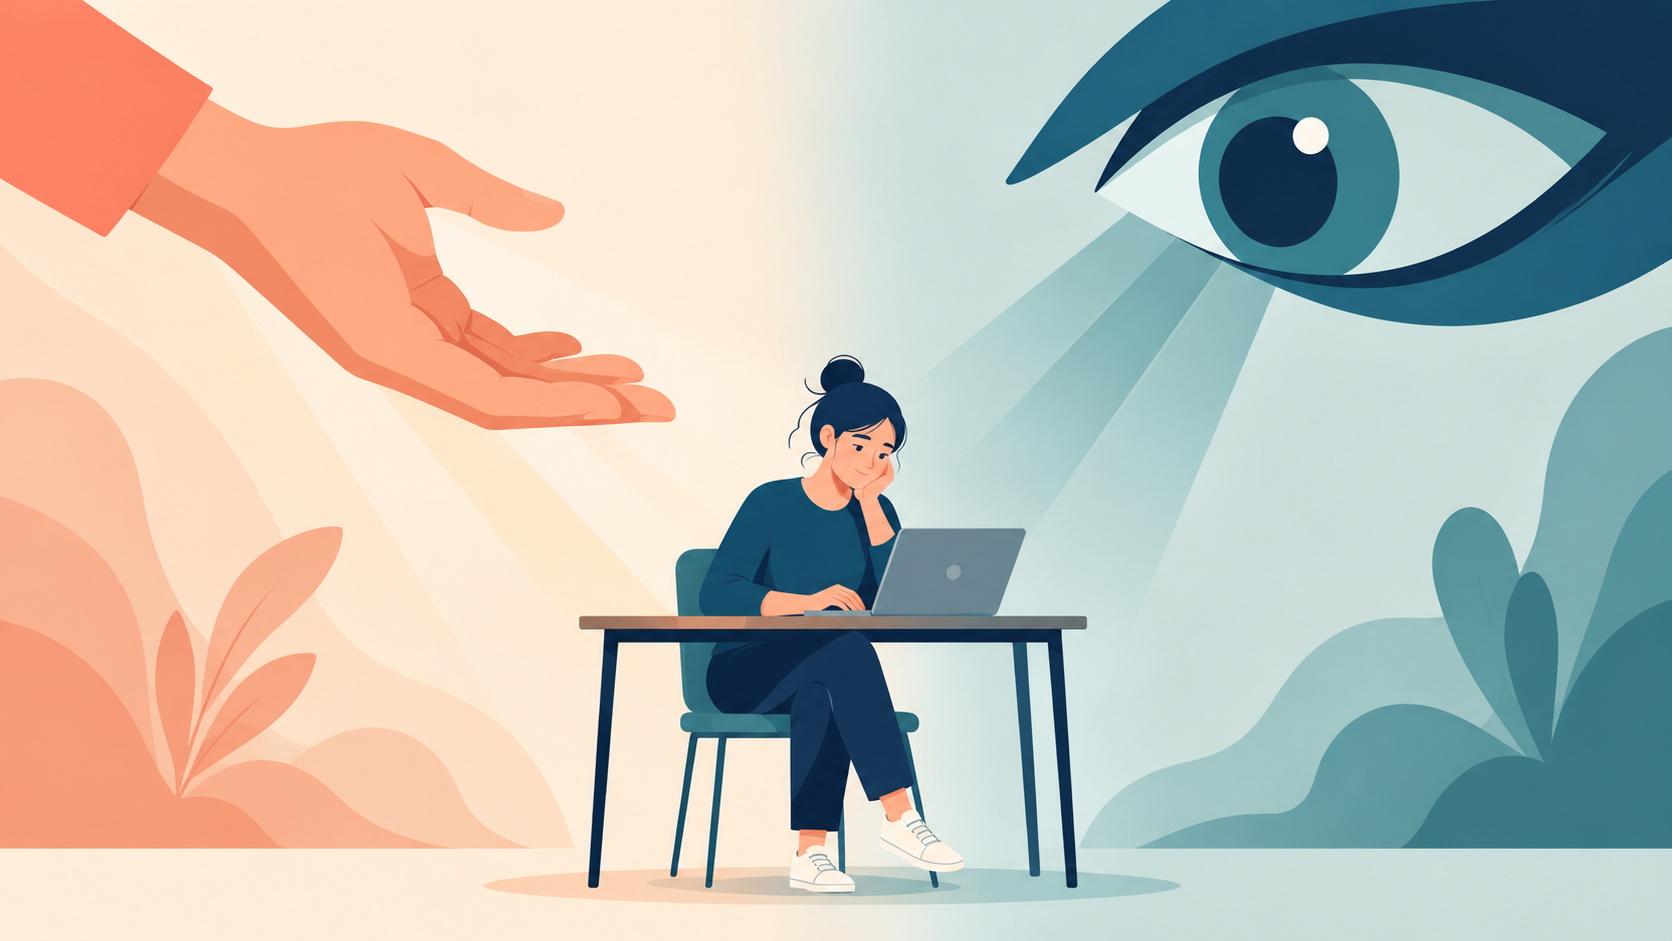
Used less well, it is a system that watches every student, infers things about them, and acts on those inferences. A different sentence, describing the same technology.
Both of those are true at once, and which one your institution ends up with is decided by a set of choices most people never see. Which is why it matters that Jisc refreshed its Code of Practice for Learning Analytics last month, and brought it up to date for the thing that has changed most since it was written: AI.
The code has been around since 2015, and for a long time it was the sensible, slightly dry document you were meant to have read. The refresh keeps its four core principles – that analytics should be for the benefit of students, that the data use should be valid, that the process should be transparent, and that someone should be accountable for it – and adds guidance on what those mean once AI is doing part of the work. That addition is the point. When a human analyst flagged a struggling student, you could ask them why. When a model does it, “why” becomes a harder question, and the cost of not being able to answer it goes up.
Learning analytics sits on every fault line I spend my time thinking about. You are collecting data about students, often more than they realise. You are drawing conclusions about them – this one is disengaged, this one is at risk – that may or may not be fair, and may or may not be right. And you are acting on those conclusions in ways that affect how a real person is treated. Get it right and it is support. Get it wrong and it is profiling with a kind face.
The principles in the code are not bureaucracy. They are the questions that decide which of those you have built.
Take “for the benefit of students”, the first principle and the easiest to nod along to. It sounds obvious until you ask it properly. Is this early-warning system there to help the student, or to protect the institution’s continuation figures? The two goals overlap much of the time, which is what makes it easy to stop checking whether they have come apart. A student flagged as a retention risk and a student flagged as someone who needs help are not always treated the same way, even when they are the same student.
Or transparency. Do your students know they are being tracked this way? Do they know their logins and swipe-ins feed a score that decides whether someone calls them in for a chat? There is a version of learning analytics done with students, who understand it and can see their own data, and a version done to them, which they discover by accident. The technology is identical. The relationship is not.
The AI layer sharpens all of it. When a model decides who gets flagged, you are in the territory I wrote about with automated decisions: can you explain how it reached its conclusion, is there a real person who can overrule it, and have you checked whether it flags some groups more than others for reasons that have nothing to do with how they are doing? A model trained on who struggled in the past can learn the sector’s old patterns and apply them to this year’s students, the way any model does.
There is one more trap worth naming, because it is particular to this. If you flag a student as high-risk and then treat them as high-risk, you can change the outcome you were trying to predict – for the better, if the help lands, but for the worse too, if being marked as a likely failure changes how they are taught, advised or seen. A prediction that alters the thing it predicts is a powerful tool and a hazardous one, and it needs watching.
None of this is a reason not to use learning analytics. It is a reason to treat the refreshed code as a set of live questions rather than a document to file. Before the dashboards go in, and regularly after: can we say, specifically, how this helps the student in front of us? Do students know this is happening, and can they see what we hold? When the system flags someone, is there a person deciding what happens next, with the standing to disagree with it? Have we checked whether the flagging is even-handed? And where AI is involved, could we explain a single one of its decisions to the student it was about?
Answer those, and learning analytics is one of the better things the sector has built. Fail to, and you have built a system that monitors your students and called it support. The code is the difference between the two, and the refresh is a good reason to check which one you are running.